Gemini 4 Argon Is Live: Agent Loops Work on Day One
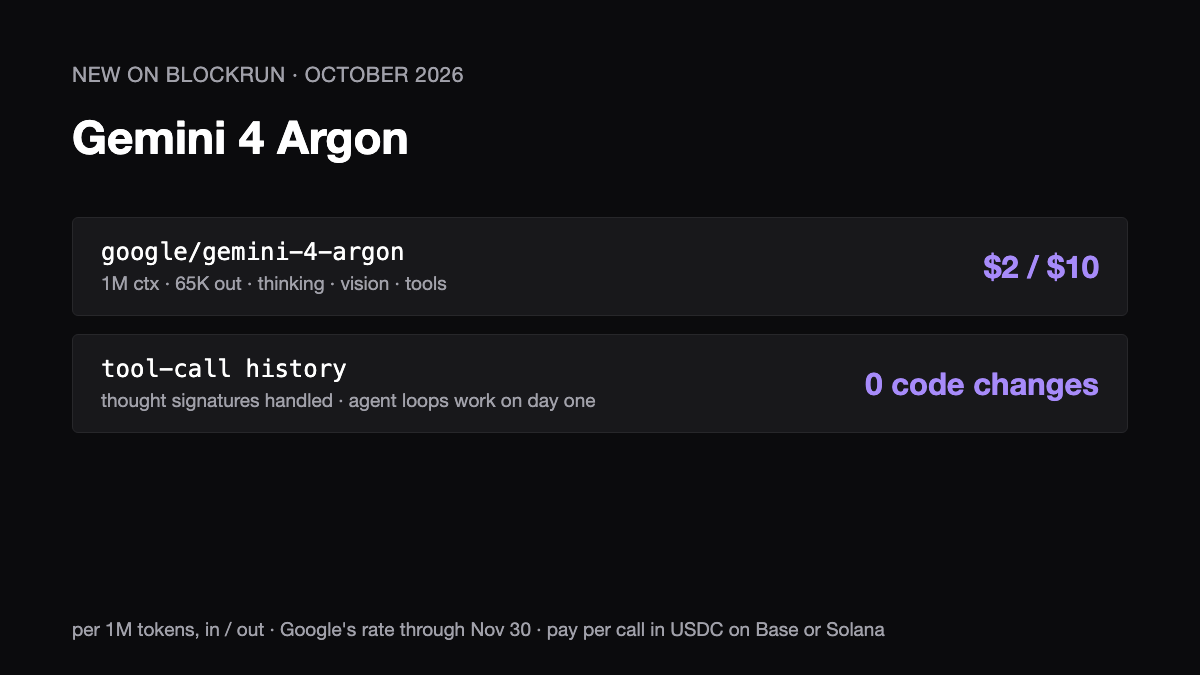
google/gemini-4-argon is live on BlockRun as of today, October 20, on Base
and on Solana. It is Google's new frontier reasoning model, built for the work that takes many
steps: agents that plan and call tools for an hour, multi-file software
changes, and math and science problems that need real thinking before an
answer.
| Model | Input / 1M | Output / 1M | Cached input / 1M | Context | Max output |
|---|---|---|---|---|---|
google/gemini-4-argon | $2.00 | $10.00 | $0.10 | 1M | 65,536 |
It thinks, it reads images, and it calls tools. Send it through the same OpenAI-compatible endpoint as every other model, with no Google account and no key of your own.
What it is for
Argon is the top of Google's lineup, above Gemini 3.1 Pro. Google built it for long-horizon work, and that is where it earns its place in a routing table:
- Agents that run for many steps. Plan, call a tool, read the result, call the next one, without losing the thread across a long session.
- Complex software engineering. A 1M-token window holds a whole codebase in the prompt, so a refactor can see every file it touches.
- Deep math and science. Thinking is on by default, so hard problems get worked through before the model commits to an answer.
At $2 / $10 it costs less per output token than Gemini 3.1 Pro ($12). For a reasoning-heavy agent, where output dominates the bill, that makes Argon the cheaper of Google's two top models as well as the stronger one.
The thing that would have broken your agent
Gemini 4 changes one rule that every OpenAI-format agent runs into on its second turn.
When Gemini calls a tool, it attaches a thought signature to the call, an opaque token that ties the call to the reasoning that produced it. When your agent sends the conversation back for the next step, Google expects that signature on every earlier tool call in the history.
The OpenAI chat format has nowhere to keep it. tool_calls carry an id, a
name and arguments, and that is all. So any agent built on the OpenAI format,
which is nearly every agent framework, sends Gemini a history with no
signatures in it.
Gemini 3 let that go. Gemini 4 Argon refuses it. We tested it directly before listing the model: a history with an earlier tool call and no signature comes back as an HTTP 400, "Function call is missing a thought_signature". On an unadapted integration that is not an occasional error. It is every multi-step agent loop, failing on step two.
BlockRun fills the signature in. Every earlier tool call in the history goes
to Gemini with the placeholder signature Google documents for exactly this
case, history that was produced without one. We then ran a real two-round
tool loop through both our streaming and non-streaming paths: Argon answered
itself, with the correct next tool call and finish_reason: "tool_calls", and
no fallback stepped in.
So nothing changes on your side. Point your existing agent at
google/gemini-4-argon and the loop runs.
What it costs
$2 in, $10 out per 1M tokens, which is Google's own rate. We pass LLM tokens through at cost, so what you pay is what Google charges.
That rate runs through November 30, 2026. From December 1, Google's price for Argon is $4 / $20, with cached input at $0.20, and ours moves with it on the same day. If you are going to run a large job on Argon, this is the month to do it.
Two more things move the per-call bill:
- Thinking tokens are output tokens. They bill at the $10 rate and count
against the same 65,536-token output allowance as the answer. Give
reasoning-heavy calls room in
max_tokens. - There is no long-context surcharge. Unlike Gemini 3.1 Pro, Argon has no higher tier above 200K prompt tokens. A 900K-token prompt bills at the same $2 per 1M as a 9K one.
If it is unavailable
Argon falls back to google/gemini-3.5-flash ($1.50 / $9): same maker, the
same 1M context, and the same thinking, vision and coding capabilities. A
rescue is never a smaller model standing in for the one you chose, and never
costs more than the request you sent.
Calling it
The chat endpoint is OpenAI-compatible, and the SDK handles the payment:
from blockrun_llm import LLMClient

client = LLMClient()  # wallet from BLOCKRUN_WALLET_KEY or ~/.blockrun/.session
print(client.chat("google/gemini-4-argon", "Plan the migration of this service to async, step by step."))
On Solana, the same call with the Solana client, through the sol.blockrun.ai
gateway:
from blockrun_llm import SolanaLLMClient

client = SolanaLLMClient()  # wallet from SOLANA_WALLET_KEY; pays USDC on Solana
print(client.chat("google/gemini-4-argon", "Prove this invariant holds, then write the test."))
Tool calls use the standard OpenAI shape. Send the history back as you would to any other model, with no signatures:
curl https://blockrun.ai/api/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "X-PAYMENT: $PAYMENT_HEADER" \
  -d '{
    "model": "google/gemini-4-argon",
    "tools": [{"type": "function", "function": {
      "name": "bash", "description": "run a shell command",
      "parameters": {"type": "object", "properties": {"command": {"type": "string"}}, "required": ["command"]}
    }}],
    "messages": [
      {"role": "user", "content": "List the files, then show the date."},
      {"role": "assistant", "content": "", "tool_calls": [{"id": "c1", "type": "function",
        "function": {"name": "bash", "arguments": "{\"command\":\"ls\"}"}}]},
      {"role": "tool", "tool_call_id": "c1", "content": "a b c"}
    ]
  }'
The first response is a 402 carrying the exact price. Sign it, retry, and the next tool call comes back. Teams can use an API key with a card or invoice instead, and an autonomous agent can pay per call from its own wallet in USDC on Base or Solana over x402, with no account at all.
Try it
The full catalog, with live prices, is at blockrun.ai/models, and the docs cover each model's request rules. Send your agent's next task to Argon, and the price comes back before the work does.